Threat hunting frameworks provide structured methodologies—hypothesis-driven, intelligence-led, or situational awareness approaches—that guide analysts through the hunting process. Using a consistent framework improves repeatability and makes it easier to measure and communicate results.
Key takeaways
- MITRE ATT&CK is the most widely used threat hunting framework—it organizes attacker behavior into tactics and techniques, serving as both a hypothesis library and a coverage map; ATT&CK-based hunting focuses on behaviors rather than artifacts, which matters because infrastructure rotates but TTPs persist.
- TaHiTI structures intelligence-driven hunting; the Sqrrl loop formalizes the hypothesis-to-detection-improvement cycle; the Pyramid of Pain prioritizes hunting by how costly evasion is for attackers—TTPs sit at the top because changing them forces fundamental operational changes.
- Most mature programs combine frameworks: ATT&CK as the primary technique library, Sqrrl’s continuous improvement philosophy, and the Pyramid of Pain for prioritization.
- Frameworks tell you how to think about hunting. To actually run a hunt, you need a repeatable process, a template, and metrics that show whether it’s working—all covered below.
Threat hunting frameworks provide structured approaches for conducting hunts, turning “look for threats” into a systematic, repeatable methodology with defined processes and measurable coverage. The major frameworks each emphasize different aspects of hunting: MITRE ATT&CK maps attacker behaviors, TaHiTI structures intelligence-driven hunting, the Sqrrl loop and PEAK formalize the hunt cycle, the Diamond Model connects the pieces of an intrusion, the Pyramid of Pain prioritizes hunting by how much it costs attackers to evade, and the Hunt Maturity Model measures how far along your program is.re hunting programs combine elements of multiple frameworks rather than adhering rigidly to one.
See how MDR works in real-time with our on-demand demo
See how our 24×7 SOC actually protects you—no sales meeting required.
MITRE ATT&CK for threat hunting
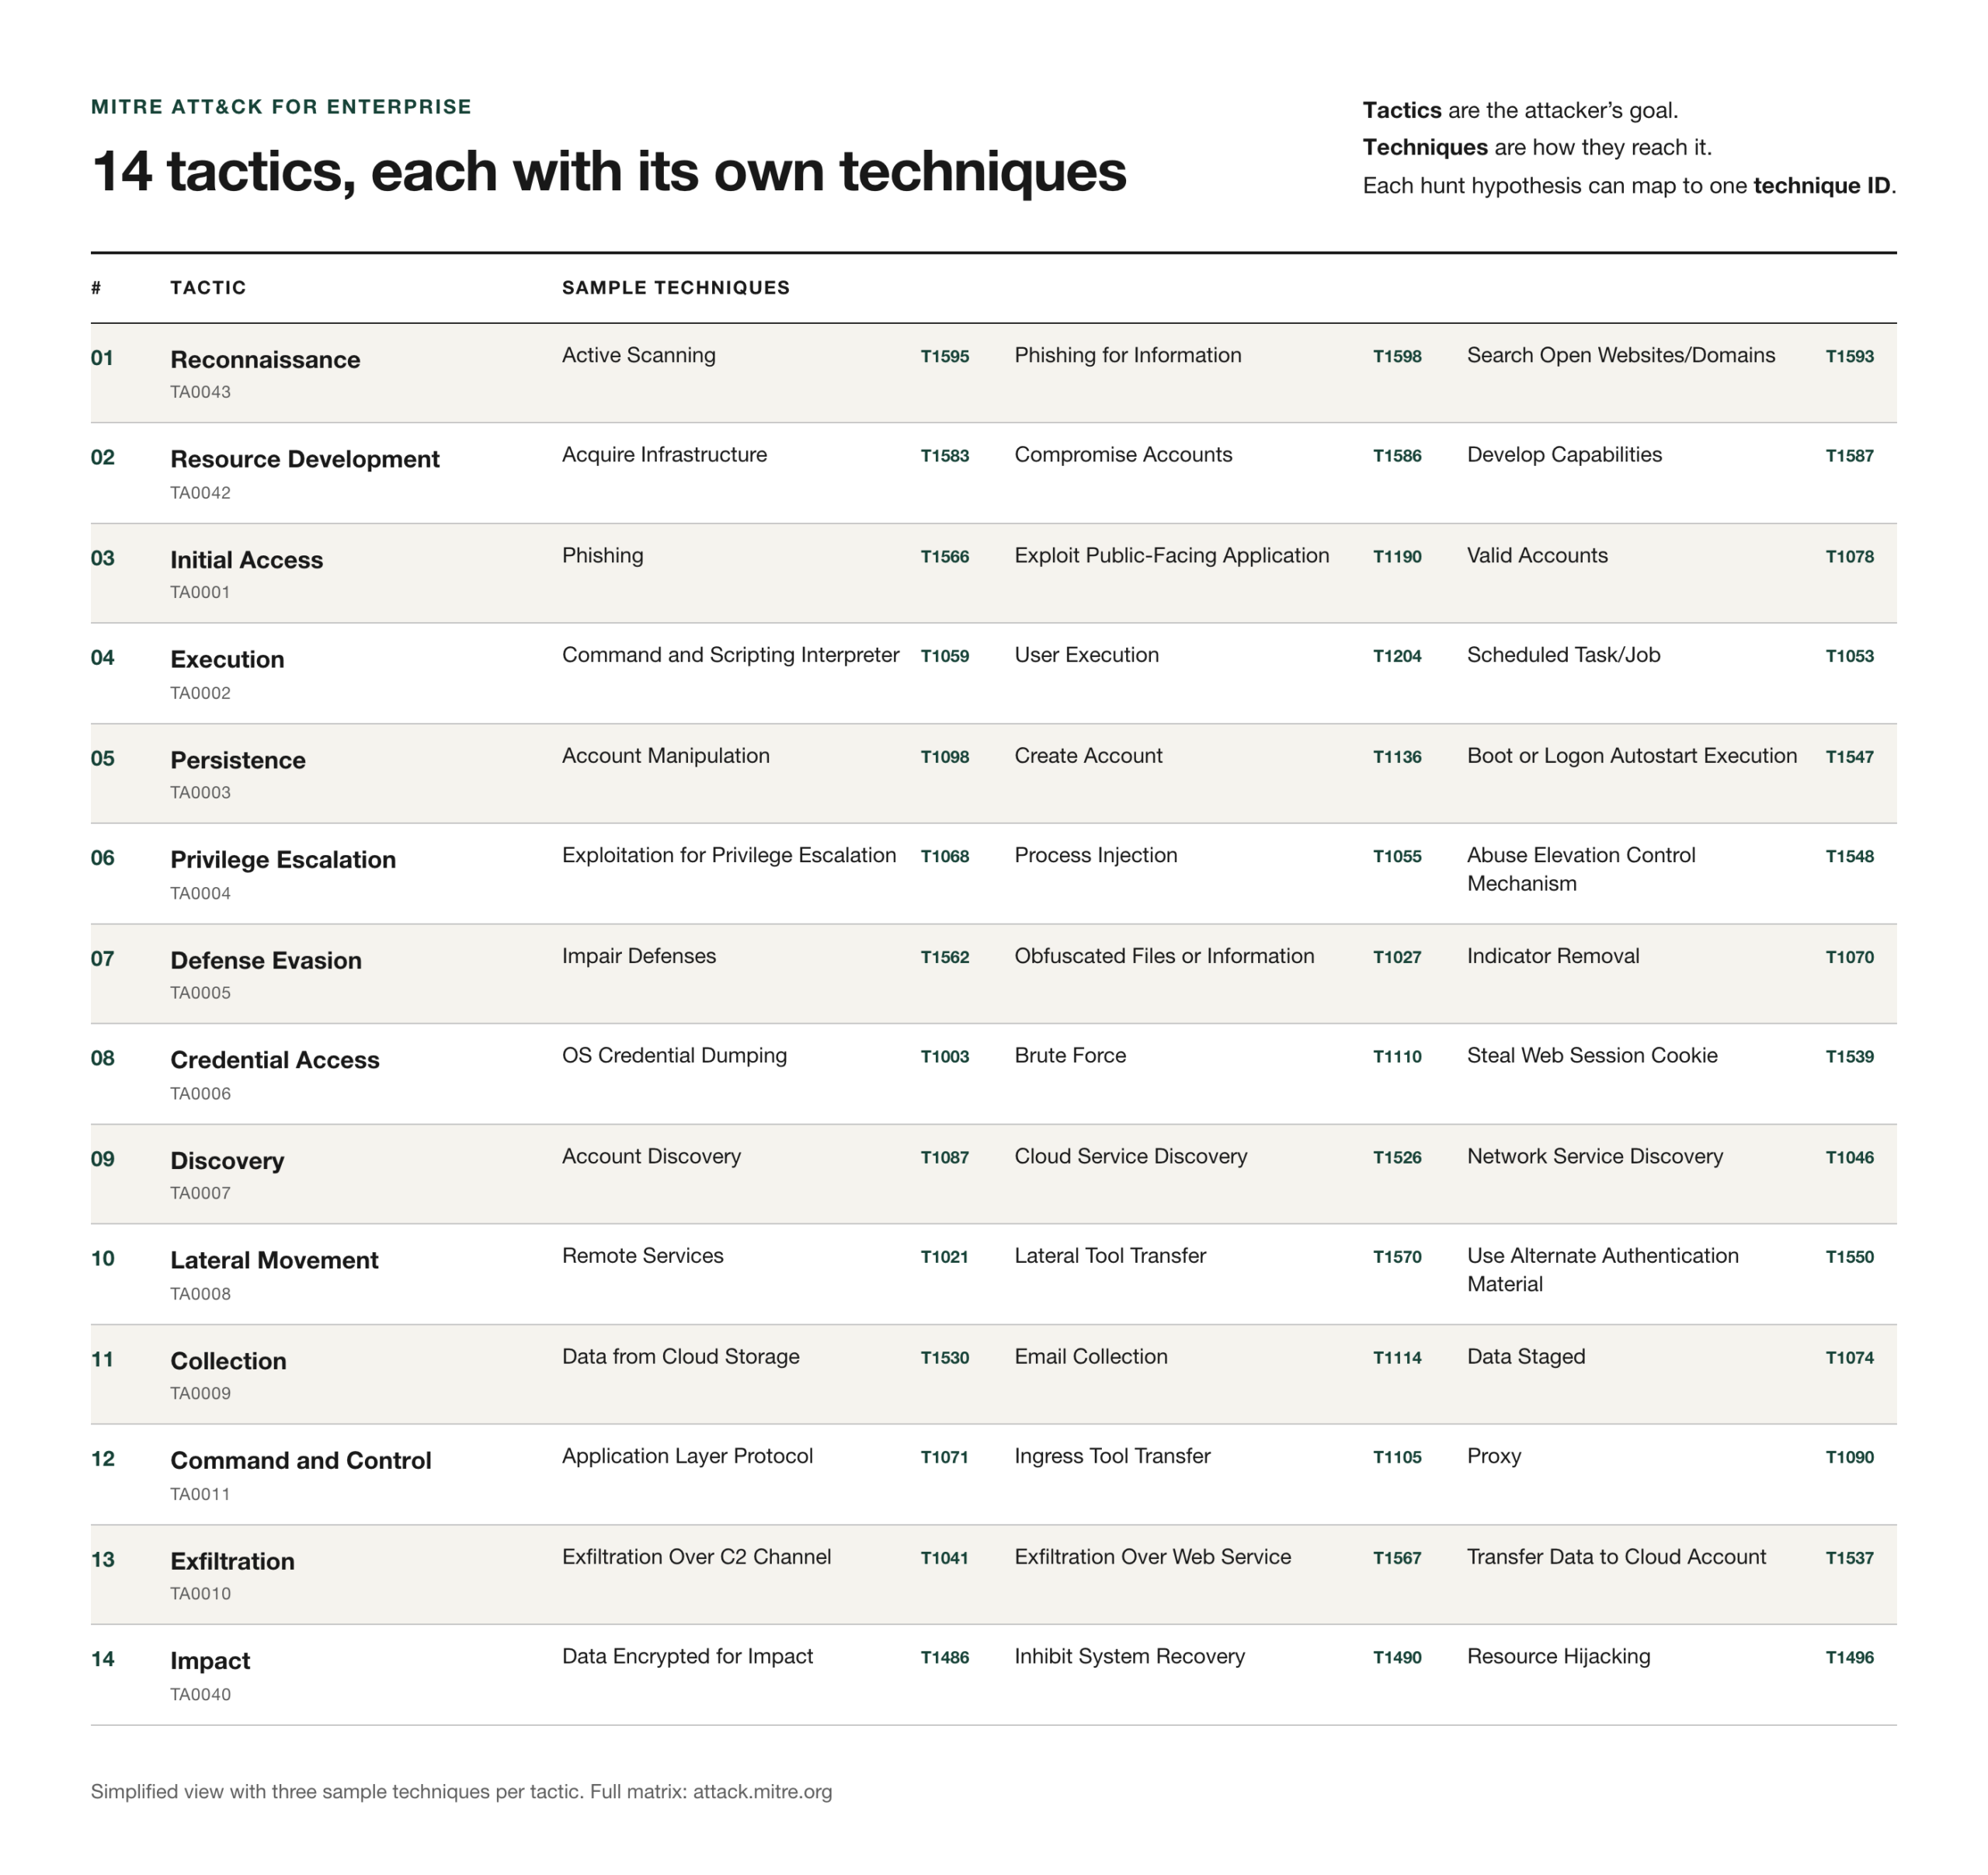
MITRE ATT&CK is the most widely used framework in threat hunting because it provides a comprehensive, community-maintained taxonomy of attacker behaviors organized in a way that maps directly to hunting activities.
The framework organizes adversary behavior into tactics (what the attacker is trying to accomplish—initial access, persistence, lateral movement, etc.) and techniques (how they accomplish it). For hunters, ATT&CK serves two key functions: first, as a library of hunting hypotheses—each technique is a potential behavior to search for in your environment. Second, as a coverage map—by tracking which techniques you have active detections or hunting coverage for, you can systematically identify and close gaps.
ATT&CK-based hunting is particularly powerful because attacker techniques are more durable than indicators. Infrastructure rotates; techniques persist. Hunting for behaviors rather than artifacts produces more lasting defensive value.
The TaHiTI framework
Targeted Hunting integrating Threat Intelligence (TaHiTI) is a structured framework for intelligence-driven threat hunting developed by the financial sector security community. It provides a formal methodology for translating threat intelligence into hunting activities, with defined stages for intelligence intake, hunt planning, execution, and documentation.
TaHiTI’s core contribution is making the intelligence-to-hunt connection explicit and auditable. Rather than informal processes where a threat analyst reads an intelligence report and a hunter independently decides whether to act on it, TaHiTI defines how intelligence flows into hunt planning, what gets hunted and why, and how findings are documented and fed back into the intelligence cycle.
Organizations in regulated industries (particularly financial services) find TaHiTI valuable because it produces an auditable record of how threat intelligence is operationalized.
The Sqrrl hunting loop
The Sqrrl hunting loop (developed by the company that pioneered much of modern threat hunting methodology before being acquired by AWS) formalizes the iterative hypothesis-driven hunting cycle into four stages: Create hypothesis → investigate via tools and techniques → uncover new patterns and TTPs → inform and enrich analytics.
The loop’s key insight is that hunting isn’t linear, it’s cyclical. Each hunt produces findings that improve automated detection (the final stage feeds back into the beginning), and each improvement to detection generates new hypotheses about what still isn’t being caught. The Sqrrl loop makes this continuous improvement relationship explicit.
The Pyramid of Pain
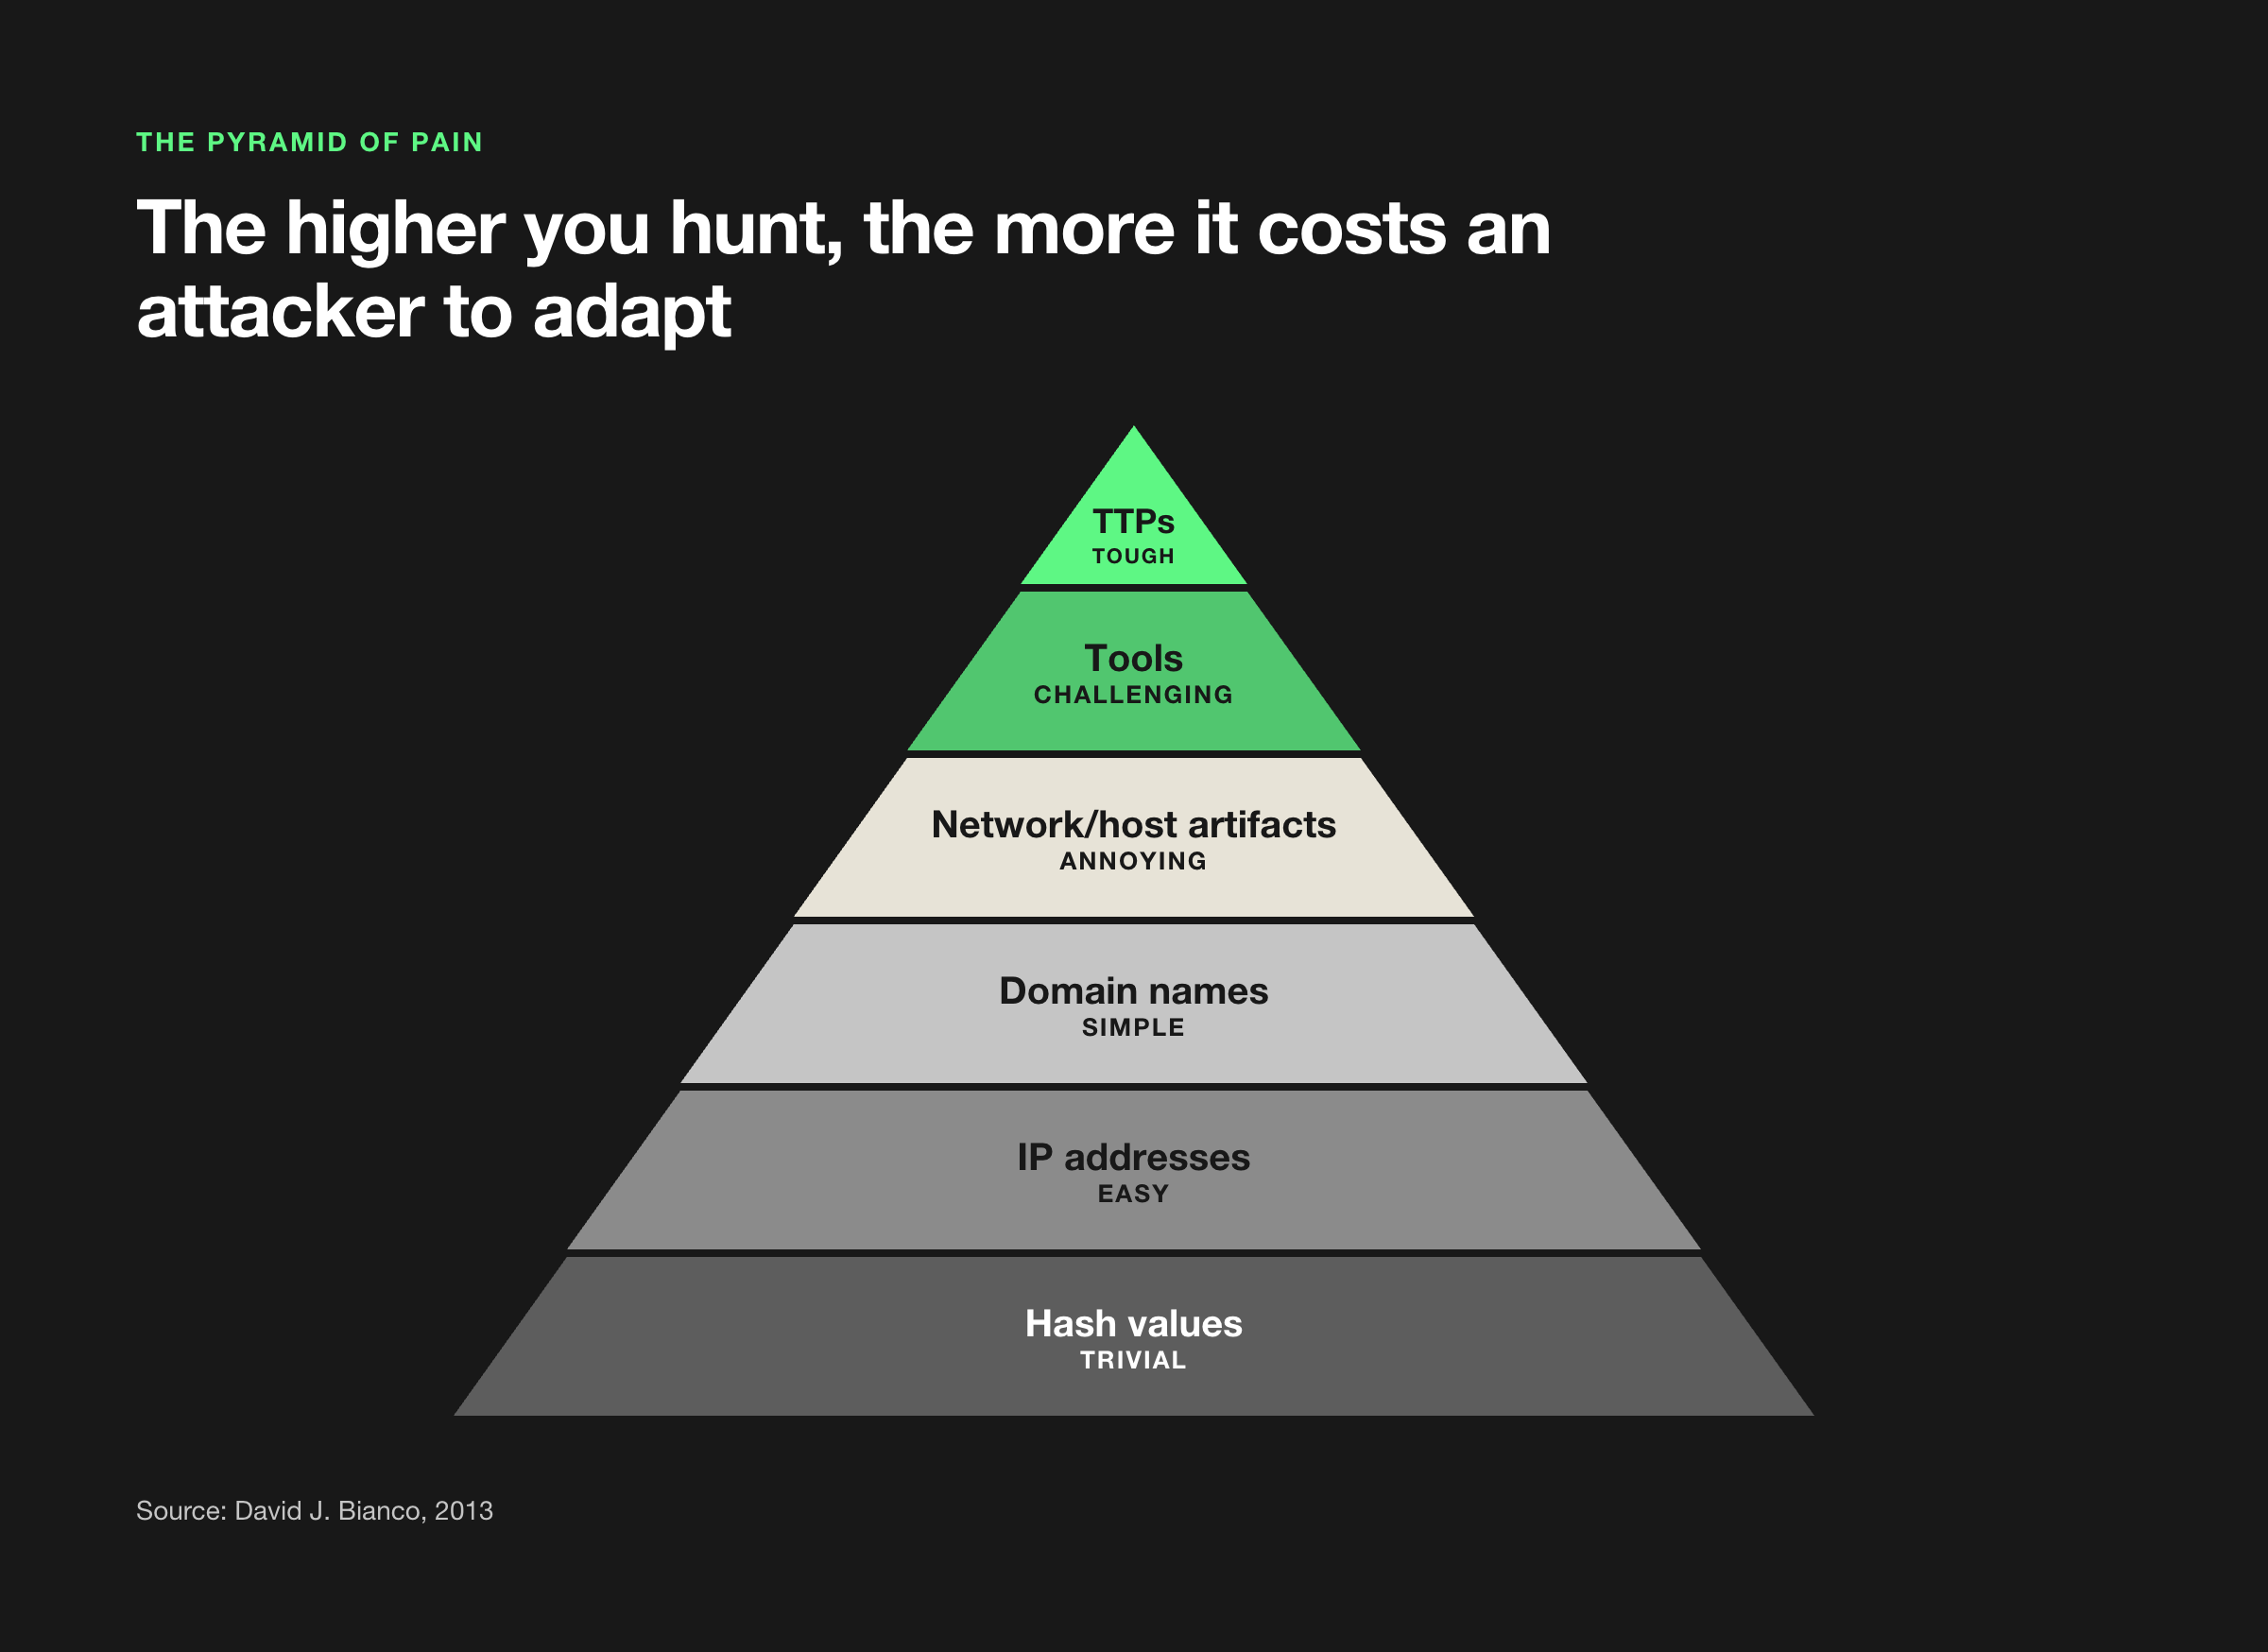
The Pyramid of Pain, developed by security researcher David Bianco, categorizes indicators of compromise by how difficult they are for attackers to change. At the bottom: hash values (trivially changed). Moving up: IP addresses, domain names, network/host artifacts. At the top: tools and TTPs (expensive for attackers to change).
For hunters, the pyramid of pain provides a prioritization framework. Hunting for and detecting attacker TTPs (behaviors at the top of the pyramid) forces attackers to fundamentally change how they operate, which is costly and difficult. Hunting for file hashes forces them to recompile malware, which takes five minutes.
Building a hunting program that focuses on the top of the pyramid produces far more lasting defensive value than one focused on indicator-based hunting.
Kill chain-based hunting
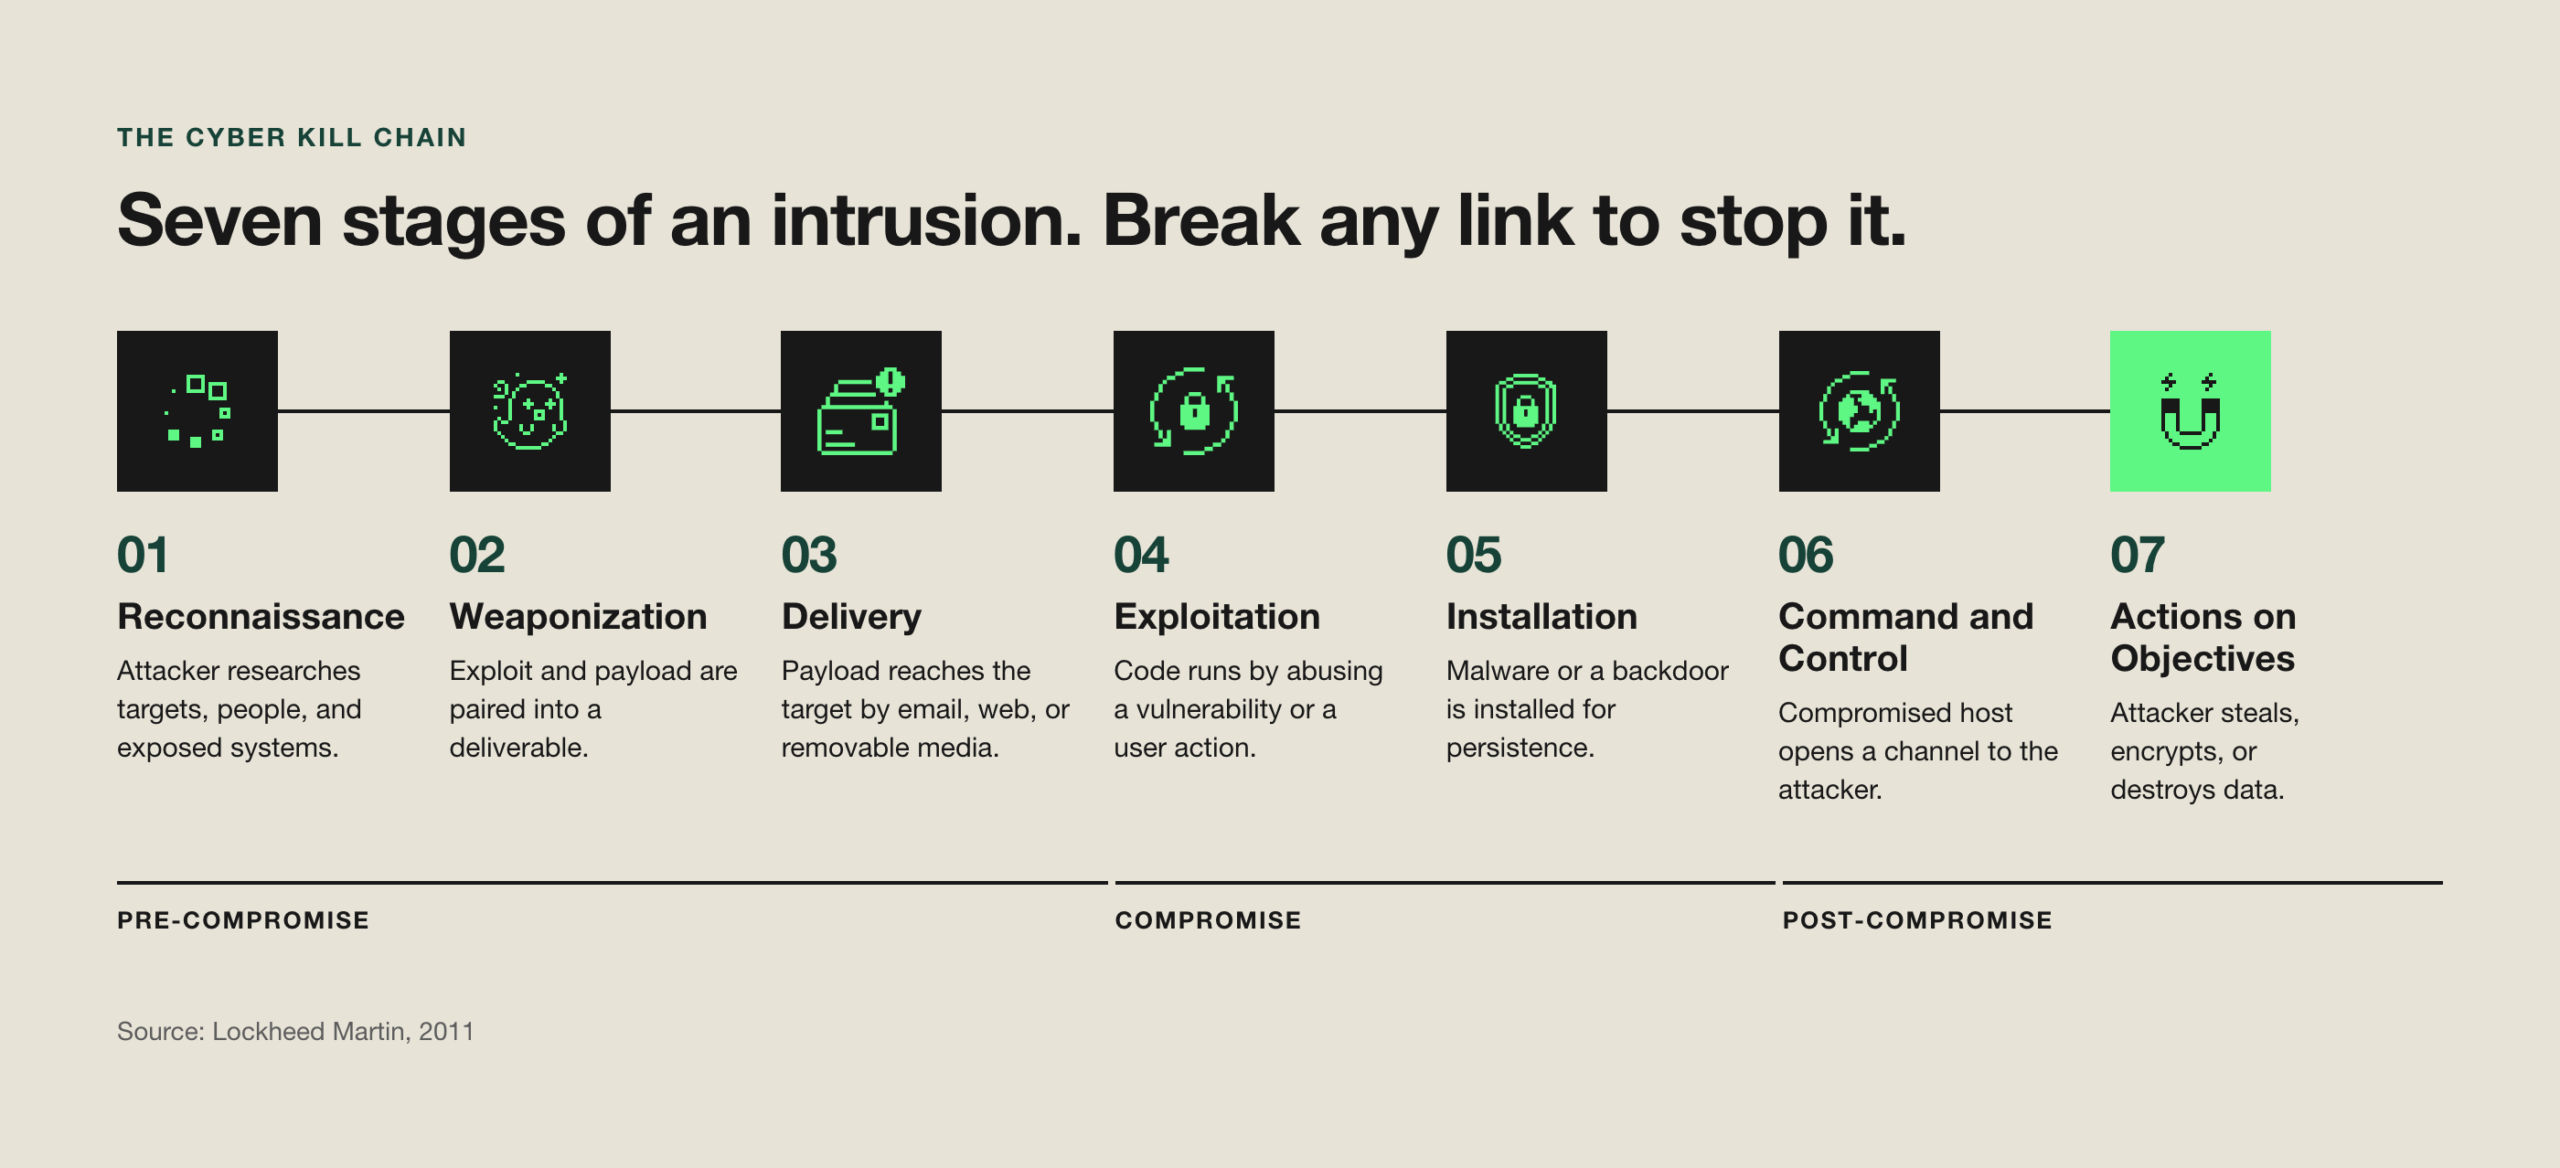
The cyber kill chain (originally developed by Lockheed Martin) models attacker intrusions as a sequential set of stages: reconnaissance, weaponization, delivery, exploitation, installation, command and control, and actions on objectives. Kill chain-based hunting focuses on detecting and disrupting attacker activity at specific stages in this sequence.
The strategic insight of kill chain-based hunting is that earlier disruption is more valuable. Stopping an attacker at the delivery or exploitation stage prevents all subsequent damage. Hunting for initial access and early-stage activity, even though it’s harder to detect, has higher ROI than focusing hunting exclusively on post-exploitation stages.
In practice, most organizations combine kill chain and ATT&CK frameworks: the kill chain provides strategic prioritization (focus earlier stages), ATT&CK provides the specific technique inventory for each stage.
The PEAK framework
PEAK (Prepare, Execute, and Act with Knowledge) is a hunting framework from Splunk’s SURGe team. It’s built to be repeatable, and it’s the closest thing to a full operating manual of the frameworks on this page.
PEAK fills a gap the other frameworks leave open: not every hunt starts with a hypothesis. It defines three hunt types:
- Hypothesis-driven hunts start with a testable idea about attacker behavior, usually drawn from ATT&CK, threat intelligence, or a recent incident.
- Baseline hunts start by learning what normal looks like in your environment, then look for what deviates. They’re useful when you don’t yet know what to look for.
- Model-assisted threat hunts (M-ATH) use machine learning or statistical models to surface outliers that a human then investigates.
Each hunt moves through three phases:
- Prepare. Pick a topic, research it, confirm you have the data, and set the scope.
- Execute. Run the hunt, analyze results, and refine your searches as you learn.
- Act with knowledge. Document what you found, hand off confirmed threats, build detections from what worked, and share what you learned.
Use PEAK when you want one consistent process for your team, especially if you run more than one type of hunt.
The Diamond Model of intrusion analysis
The Diamond Model, published in 2013 by Sergio Caltagirone, Andrew Pendergast, and Christopher Betz, breaks every intrusion event into four connected features:
- Adversary: who’s behind the activity
- Capability: the tools, malware, and techniques they use
- Infrastructure: the domains, IP addresses, and accounts they operate from
- Victim: the target, including the people, systems, and data involved
Each feature sits at a corner of a diamond, and each connects to the other three. That’s what makes it useful for hunting: if you find one feature, you can pivot to the others. A suspicious domain (infrastructure) leads you to the hosts that contacted it (victim), the tooling those hosts ran (capability), and, over time, a picture of the adversary.
The model also tracks meta-features like timestamp, attack phase, result, and methodology, so you can build activity threads that show how an intrusion unfolded.
Use the Diamond Model to expand a single lead into a full picture. It works best in the middle of a hunt, when you’ve found something and need to decide where to look next.
The Hunting Maturity Model
The Hunting Maturity Model (HMM), created by David Bianco (also the author of the Pyramid of Pain), isn’t a way to run a hunt. It’s a way to measure how good your hunting program is. It has five levels:
| Level | Name | What it looks like |
|---|---|---|
|
HMM0 |
Initial | You rely on automated alerting. Little or no routine data collection, and no hunting. |
|
HMM1 |
Minimal | You search for indicators from threat intelligence reports. You collect a moderate amount of data. |
|
HMM2 |
Procedural | You follow hunting procedures written by others and apply them to rich data sets. |
|
HMM3 |
Innovative | Your team writes its own new hunting procedures and techniques. |
|
HMM4 |
Leading | You automate your best hunts so analysts are free to build new ones. |
Most teams that say they hunt are at HMM1 or HMM2. That’s not a failure. The model is useful because it tells you what to do next: HMM1 teams need better data, HMM2 teams need to start writing their own hunts, and HMM3 teams need to turn proven hunts into detections.
Use the HMM to set a realistic goal for your program and to explain to leadership why more data and more analyst time matter.
Choosing and combining frameworks
No single framework is complete on its own. ATT&CK provides the best technique inventory but doesn’t dictate process. TaHiTI provides excellent process structure but is most valuable in intelligence-heavy environments. The Sqrrl loop provides the right mental model for continuous improvement but is light on specific methodology. The Pyramid of Pain provides excellent prioritization guidance but isn’t a hunting methodology on its own. Add PEAK as your day-to-day process, the Diamond Model for pivoting during a hunt, and the Hunt Maturity Model to measure progress.
Most mature hunting programs use ATT&CK as their primary technique library and coverage map, incorporate the Sqrrl loop’s continuous improvement philosophy into their program design, apply Pyramid of Pain thinking to prioritize where to invest hunting effort, and use TaHiTI-style documentation when operationalizing specific intelligence.
| Pyramid of pain | MITRE ATT&CK | Cyber kill chain | TaHITI | Sqrrl hunting loop | PEAK | Diamond Model | Hunt Maturity Model | |
|---|---|---|---|---|---|---|---|---|
|
Created by |
Security researcher David Bianco | MITRE, maintained by the. community | Lockheed Martin | The financial sector security community | Sqrrl, later acquired by AWS | Splunk SURGe | Caltagirone, Pendergast, and Betz | David Biano |
|
What it does |
Ranks indicators of compromise by how hard they are for attackers to change | Organizes attacker behavior into tactics (the goal) and techniques (the how) | Models an intrusion as seven sequential stages | Turns threat intelligence into hunts, from intake and planning to execution and documentation | Formalizes hunting as a four-stage cycle, from hypothesis to better detections | Defines three hunt types and a three-phase process | Breaks an intrusion into adversary, capability, infrastructure, and victim | Rates a hunting program on a five-level scale |
|
Use it to |
Prioritize where to invest hunting effort | Generate hypotheses and map detection coverage | Focus hunting on earlier stages, where disruption is worth more | Keep an auditable record of how intelligence is operationalized | Feed hunting finds back into automated detection | Run consistent hunts of different types | Pivot from one lead to the full picture | Set goals and show progress to leadership |
|
Limitation |
Isn’t a hunting methodology on its own | Doesn’t dictate process | Doesn’t list specific techniques; pair it with an ATT&CK | Most valuable in intelligence-heavy environments | Light on specific methodology | Less focused on intelligence intake than TaHiTI | Describes events but doesn’t dictate a hunt process | Measures a program, not individual hunts |
How to run a hunt: step by step
Frameworks tell you how to think about hunting. This is the process they all share. Treat it as a loop, because the last step feeds the first.
- Pick a trigger. Start with a reason to hunt: a new ATT&CK technique relevant to your industry, a threat intelligence report, a recent incident, a detection gap, or an anomaly in a baseline.
- Write a hypothesis. Make it specific and testable. “Attackers may be dumping credentials” is too broad. “An attacker with local admin could be reading LSASS memory on servers that don’t normally run security tools (T1003.001)” is a hunt.
- Confirm your data. Check that you have the logs and telemetry to prove or disprove the hypothesis, and that they go back far enough. If you don’t, that’s your first finding.
- Plan the hunt. Define scope (which systems, users, and time window), write your queries, and decide in advance what counts as suspicious, what counts as normal, and when you’ll stop.
- Run it and pivot. Execute your searches. When something looks off, pivot using the Diamond Model: from a host to a user, from a process to a network connection, from a domain to every system that touched it.
- Validate and escalate. Rule out benign explanations. If you confirm malicious activity, stop hunting and hand it to incident response.
- Document the result. Record what you searched, what you found, and what you ruled out. A hunt that finds nothing is still a result. It tells you that technique isn’t present in that scope today.
- Turn it into detection. If the hunt worked, convert the logic into an automated detection so you don’t have to hunt for it again. If it surfaced a visibility gap, file that too.
- Measure and repeat. Add the hunt to your coverage map, record your metrics, and pick the next trigger.
Hunt template
Use one template for every hunt so results are comparable and easy to hand off. Copy this and adapt it.
| Field | What to record |
|---|---|
|
Hunt name and ID |
A short name and a unique ID so you can find it later |
|
Hunter and date |
Who ran it and when |
|
Hunt type |
Hypothesis-driven, baseline, or model-assisted |
|
Trigger |
What prompted the hunt: intel, incident, gap, or ATT&CK technique |
|
Hypothesis |
One or two sentences, specific and testable |
|
ATT&CK mapping |
Tactic, technique, and sub-technique IDs |
|
Scope |
Systems, users, environments, and time window |
|
Data sources |
Logs and telemetry used, plus any gaps found |
|
Queries and logic |
The exact searches or analytics you ran |
|
Benign baseline |
What normal looks like for this behavior |
|
Findings |
What you found, including false positives and benign matches |
|
Outcome |
Confirmed threat, no evidence found, or inconclusive |
|
Escalation |
Incident ticket or handoff, if any |
|
Follow-up |
New detection, visibility fix, or new hypothesis |
|
Time spent |
Analyst hours, for tracking effort |
How to measure hunt effectiveness
A hunting program that can’t show its value gets cut first. But “number of threats found” is the wrong headline metric. A good hunt in a clean environment finds nothing. These KPIs measure whether your program is improving your defenses:
- Hunts completed per quarter. Shows whether hunting is a habit or a one-off. Track it by hunt type.
- ATT&CK coverage. The percentage of relevant techniques covered by a detection or a hunt. Use your ATT&CK map and be clear about which techniques are in scope for your threat profile.
- Hunts converted to detections. The share of hunts that produce a new automated detection. This is the best single measure of whether hunting is improving your SOC.
- Threats found by hunting. Confirmed incidents that no existing detection caught. Report this, but alongside the other KPIs.
- Visibility gaps closed. Missing log sources or telemetry that hunts surfaced, and how many were fixed.
- Time to complete a hunt. Analyst hours from trigger to documented outcome. Falling times usually mean your template and tooling are working.
- Detection quality. The false positive rate of detections that came from hunts. A hunt-born detection that floods the queue isn’t a win.
- Maturity level. Your HMM level over time.
Pick four or five, set a baseline, and review them quarterly. Don’t set targets for “threats found,” because it pushes analysts to find something instead of find the truth.
Expel’s take
Most mature threat hunting programs don’t adhere rigidly to one framework—they combine elements from several. MITRE ATT&CK is the essential starting point: it’s a concrete, actionable inventory of attacker techniques that doubles as a coverage map, showing you exactly where your detection logic has gaps. The Pyramid of Pain provides the prioritization rationale for why TTP-based hunting is more valuable than indicator-based hunting—the higher you hunt on the pyramid, the more you force attackers to change fundamental behaviors instead of just swapping out a hash. The Sqrrl loop makes explicit what every mature program implicitly knows: hunting isn’t a one-time activity, it’s a cycle that continuously feeds new detection logic back into automated defenses. If you’re just starting out, begin with ATT&CK—pick two or three techniques relevant to your threat profile and build your first hypotheses from there. Frameworks only matter if they change what happens on Tuesday morning. Pick a process, use the same template every time, and measure whether your hunts turn into detections.
Frequently asked questions
Which threat hunting framework should beginners start with?
Start with MITRE ATT&CK. It provides a concrete, actionable inventory of things to hunt for, a community of practitioners sharing hunting content built around it, and a coverage mapping approach that immediately shows where your gaps are. The Pyramid of Pain is a useful conceptual companion, as it helps prioritize where within ATT&CK to focus first.
Is MITRE ATT&CK a threat hunting framework or a detection framework?
Both. ATT&CK is equally useful for hunting (as a library of behaviors to search for) and for detection engineering (as a taxonomy for mapping your rule coverage). In threat hunting specifically, ATT&CK is used to generate hypotheses, structure hunt planning, and track coverage over time. Its versatility across both proactive and reactive security is a major reason for its widespread adoption.
Do MDR providers use these frameworks?
Yes. Most mature MDR providers structure their hunting programs around MITRE ATT&CK and use it as both a technique library and a coverage reporting tool. Sharing ATT&CK-mapped hunt coverage with customers is an increasingly common way for MDR providers to demonstrate what their hunting program actually covers.
How do frameworks help with hunt documentation?
Frameworks provide shared vocabulary that makes documentation consistent and searchable. Documenting a hunt as “investigated ATT&CK T1003.001 (LSASS Memory) across endpoint population” is far more useful than “looked for credential dumping” because it maps to a specific, queryable reference that future hunters can immediately understand and build on.
What are the steps in a threat hunt?
Pick a trigger, write a testable hypothesis, confirm your data, plan the hunt, run it and pivot, validate and escalate, document the result, turn what worked into a detection, and measure. Then start again.
What is the difference between PEAK and the Sqrrl loop?
Both describe a cycle. The Sqrrl loop is a four-stage mental model. PEAK is more operational: it defines three hunt types (hypothesis-driven, baseline, and model-assisted) and gives each hunt a prepare, execute, and act process.
How do you measure threat hunting success?
Track whether hunting improves your defenses: hunts completed, ATT&CK coverage, hunts converted into detections, visibility gaps closed, and time per hunt. Don’t treat “threats found” as the only measure, since a clean result is still valuable.
What is the Hunt Maturity Model?
A five-level scale (HMM0 through HMM4) created by David Bianco that rates a hunting program from relying on automated alerts to automating its best hunts.